A type-safe crawler API built to explore crawling, extraction, Markdown conversion, caching, rate limiting, and pipeline-oriented backend design.
Context
QuickCrawl is a type-safe crawler API built as a learning-led infrastructure project. It was inspired by products like Firecrawl, but the goal was understanding the shape of the problem, not cloning an existing product.
Problem
Crawling sounds simple until the system has to fetch pages reliably, extract metadata, convert HTML into Markdown, cache expensive work, rate-limit requests, and expose everything through an API that stays easy to extend.
Product
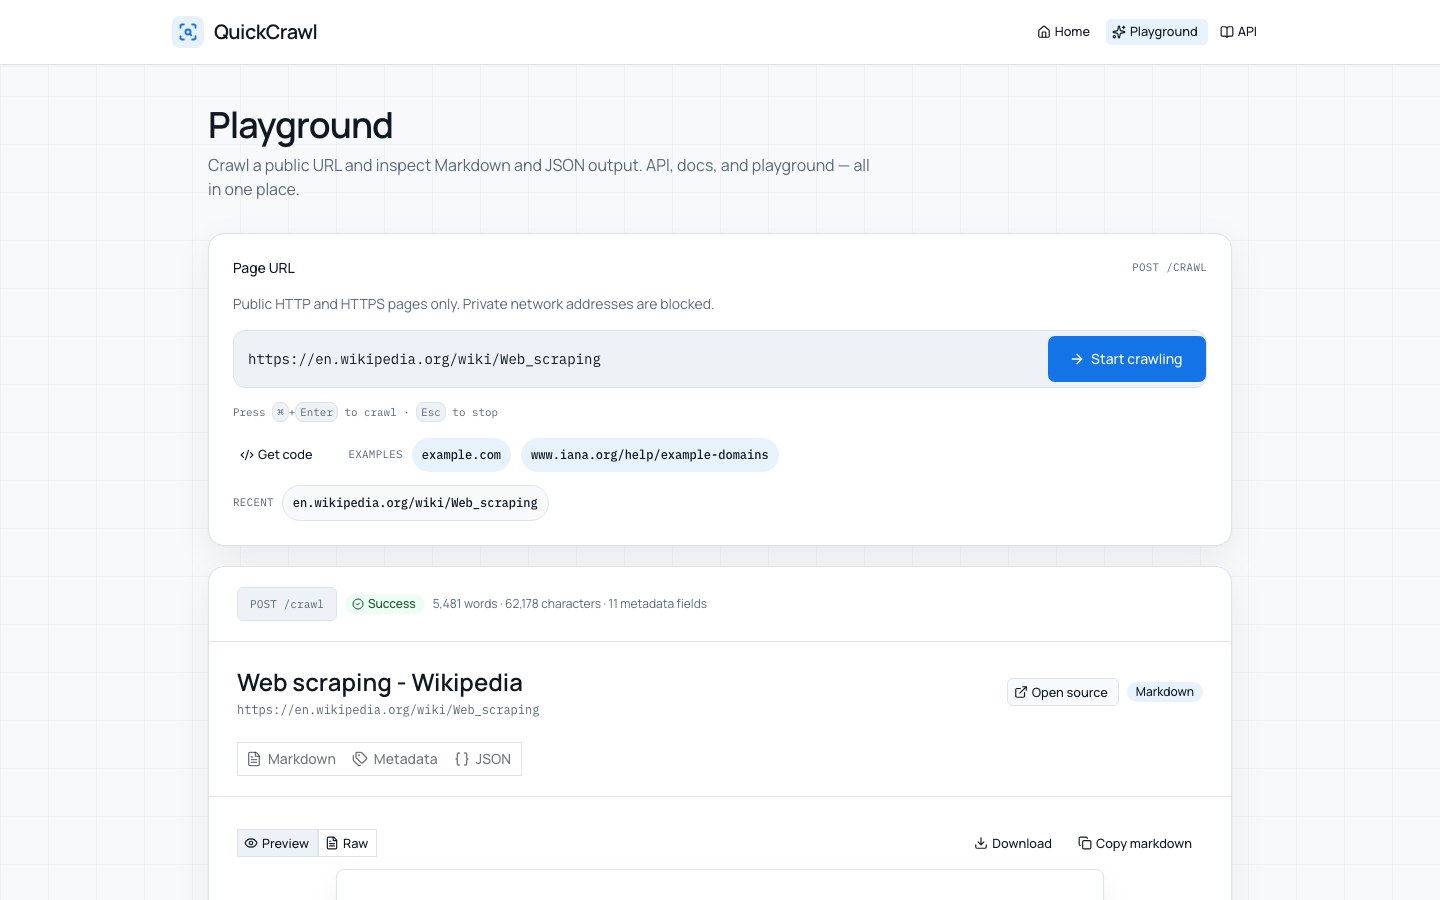
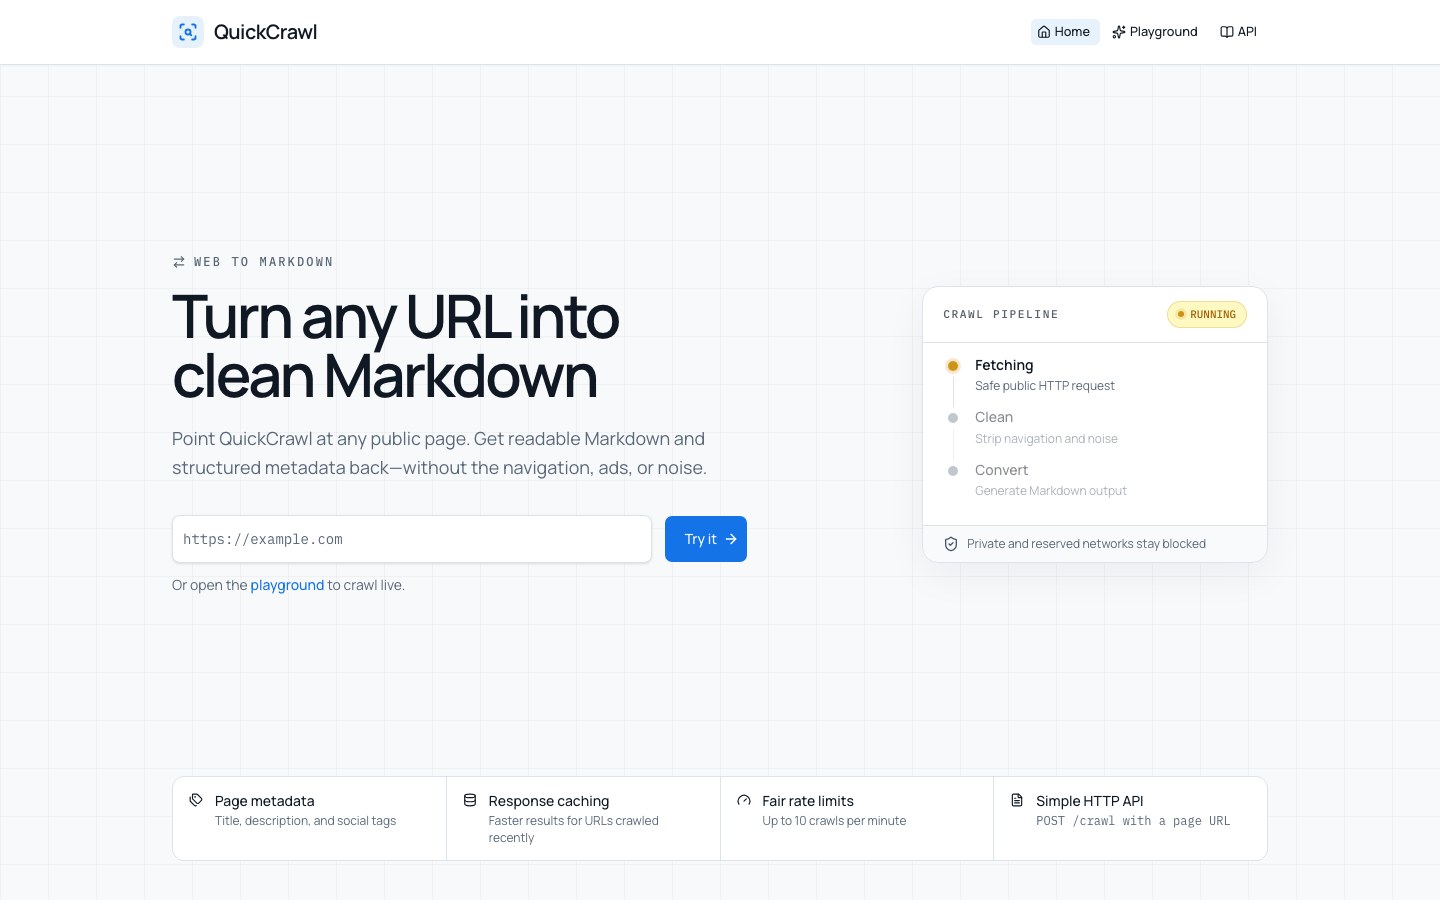
QuickCrawl exposes a small but coherent crawler API: page fetching, metadata extraction, HTML-to-Markdown conversion, request validation, caching, and rate limiting, all behind type-safe request and response contracts.
System Architecture
QuickCrawl is organised as a pipeline-oriented system with distinct responsibilities:
QuickCrawl API: the Hono-based HTTP surface with validated request/response contracts. The entry point for clients; stays thin so the pipeline can evolve independently.
Pipeline Engine: the workflow stages of fetch, extract, convert, and validate. Each stage is a discrete step rather than a tangled utility layer, which makes the system easier to reason about, test, and extend.
Cache Layer: caches expensive crawl operations so repeated requests do not re-fetch and re-process identical work.
Built with Bun and Hono for a fast, lightweight runtime. Architecture notes stay visible through documentation and decision records so the reasoning does not disappear behind the code.
Current State
QuickCrawl is a focused developer tool and architecture study. The natural next steps are deeper extraction controls, better crawl queues, and richer structured output formats.